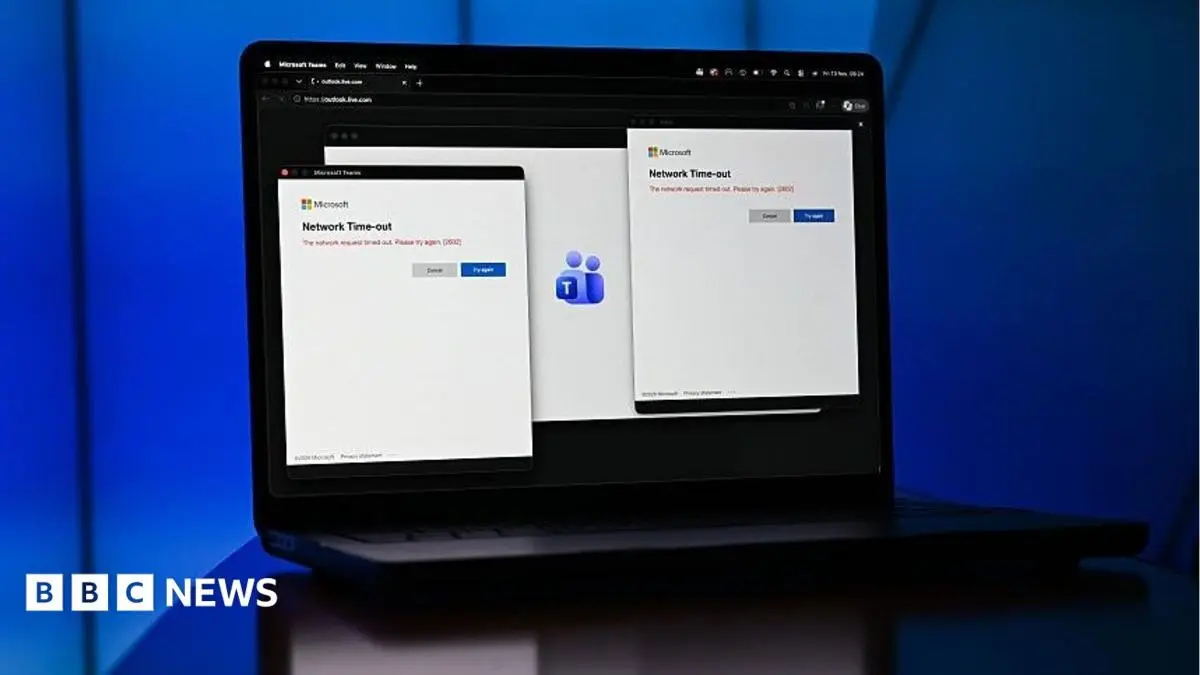
Microsoft has confirmed that its suite of cloud-based services is fully operational once again following a catastrophic worldwide outage that paralyzed business operations, government functions, and personal communications for millions of users. The tech giant announced early Saturday morning that it had successfully concluded efforts to resolve the underlying technical failure, ensuring that customers relying on Outlook, Teams, and Copilot could resume their digital workflows without further interruption.
The unprecedented disruption, which spanned more than 70 countries, served as a dramatic demonstration of the global reliance on centralized cloud infrastructure. With more than 430 million people utilizing the affected Microsoft products, the impact of the outage was felt across nearly every sector of modern life, from the internal operations of multinational corporations to the delivery of essential government and emergency services.
The Anatomy of the Disruption
The trouble began to surface on Thursday, when users across the Americas started reporting an inability to access Exchange Online mailboxes. Microsoft officially acknowledged the issue at 17:54 GMT, and within a short timeframe, it became clear that the disruption was not localized. The company warned that the incident was likely impacting Microsoft 365 services globally.
As the outage persisted into Friday, the scope of the crisis widened significantly. The failure rippled through institutional and public service sectors, affecting entities as diverse as the Japanese government, the Philippines Supreme Court, and the Australian intelligence services. In North America, the ripple effects were particularly acute, leading to disruptions in transportation networks, healthcare systems, and judicial processes. Passengers faced delays as rail services grappled with system failures, while hospitals and courtrooms found themselves unable to access the digital records and communications tools required for daily operations.
By the time the situation began to stabilize on Friday afternoon, nearly 24 hours had passed since the first reports emerged. Microsoft noted that it had restored services through a gradual, phased approach. This measured strategy was intended to manage the load on its infrastructure and ensure that the recovery remained stable as systems were brought back online.
Identifying the Cause
In the wake of the incident, Microsoft issued a formal apology for the widespread disruption, expressing deep regret for the frustration caused to its customers and partners. The company moved quickly to clarify the origins of the failure, explicitly stating that the outage was triggered by a "network capacity upgrade."
Importantly, Microsoft dismissed any speculation regarding malicious intent, confirming that the incident was not the result of a cyber-attack or an errant artificial intelligence agent. Instead, it appears to have been an internal technical oversight related to the infrastructure maintenance process. A company spokesperson emphasized that the firm understands the immense trust placed in its services by the global community and takes the responsibility of maintaining that reliability with the utmost seriousness. Microsoft has committed to releasing a comprehensive post-incident report once a full internal review has been completed, which will likely shed further light on how a routine network update managed to cascade into a global failure.
A Stark Reminder of Infrastructure Dependence
The outage has sparked an immediate and intense conversation among industry experts regarding the fragility of the modern digital landscape. For many, the incident was a sobering reminder of how significantly the global economy and vital public services have become tethered to a very small cohort of big tech providers.
Rob Demain, chief executive of the cybersecurity firm e2e-assure, characterized the event as a "stark reminder" of this dependency. "The global Microsoft outage is a stark reminder of how heavily we rely on a handful of big tech providers," Demain noted. When these centralized services experience a failure, the consequences are immediate and far-reaching, leaving organizations with little recourse.
The logistical challenge of preparing for such an event is substantial. Matt Saunders, field chief technology officer at the tech consultancy Adaptavist, pointed out that traditional disaster recovery planning often falls short when dealing with services as ubiquitous as Microsoft’s. "Classic IT disaster planning strategies suggest using a second service for resilience, but in practice, it’s almost impossible for a business to function without tools such as Microsoft," Saunders explained.
He added that while many employees may have initially welcomed a break from their email inboxes, the incident exposed a profound vulnerability. "In the wake of this outage, organisations must have a plan in place for how to work without such tools, for when incidents like this occur," Saunders said. The reliance on cloud-based ecosystems is so deep that the concept of "business continuity" is now effectively synonymous with "Microsoft continuity" for a vast majority of the professional world.
The Path to Recovery and Future Resilience
As services returned to normal on Saturday, the focus shifted to the slow process of clearing the backlog of data and ensuring that all systems remained stable. Microsoft’s timeline for the recovery showed distinct stages: by 04:36 on Friday, the company reported only "partial recovery" in certain regions. It was not until 13:32 that the company could report "broader improvements" across North America, "sustained improvements" throughout Europe, and "encouraging recovery signals" in the Asia Pacific region.
The incident has highlighted the "all-or-nothing" nature of modern cloud reliance. Because so many different tools—email, document collaboration, instant messaging, and automated AI assistance—are integrated into a single ecosystem, a failure in the underlying network capacity can effectively lock a business or government agency out of its entire digital toolkit.
While the incident is now resolved, the long-term impact on how organizations approach their IT architecture remains to be seen. Industry analysts expect that the coming weeks will feature a renewed focus on redundancy and the development of "offline-first" contingency plans. Businesses that previously viewed their reliance on Microsoft 365 as a purely operational necessity are now being forced to view it through the lens of strategic risk.
For now, Microsoft is focused on restoring full confidence among its user base. By providing transparency regarding the nature of the network upgrade error and committing to a full post-incident review, the company hopes to reassure the millions of institutions and individuals who rely on its services daily. The 24-hour disruption will likely go down in history as a pivotal case study for IT professionals, serving as a catalyst for discussions on how to build a more resilient and fault-tolerant digital future in an era defined by massive, interconnected, and centralized cloud service providers.